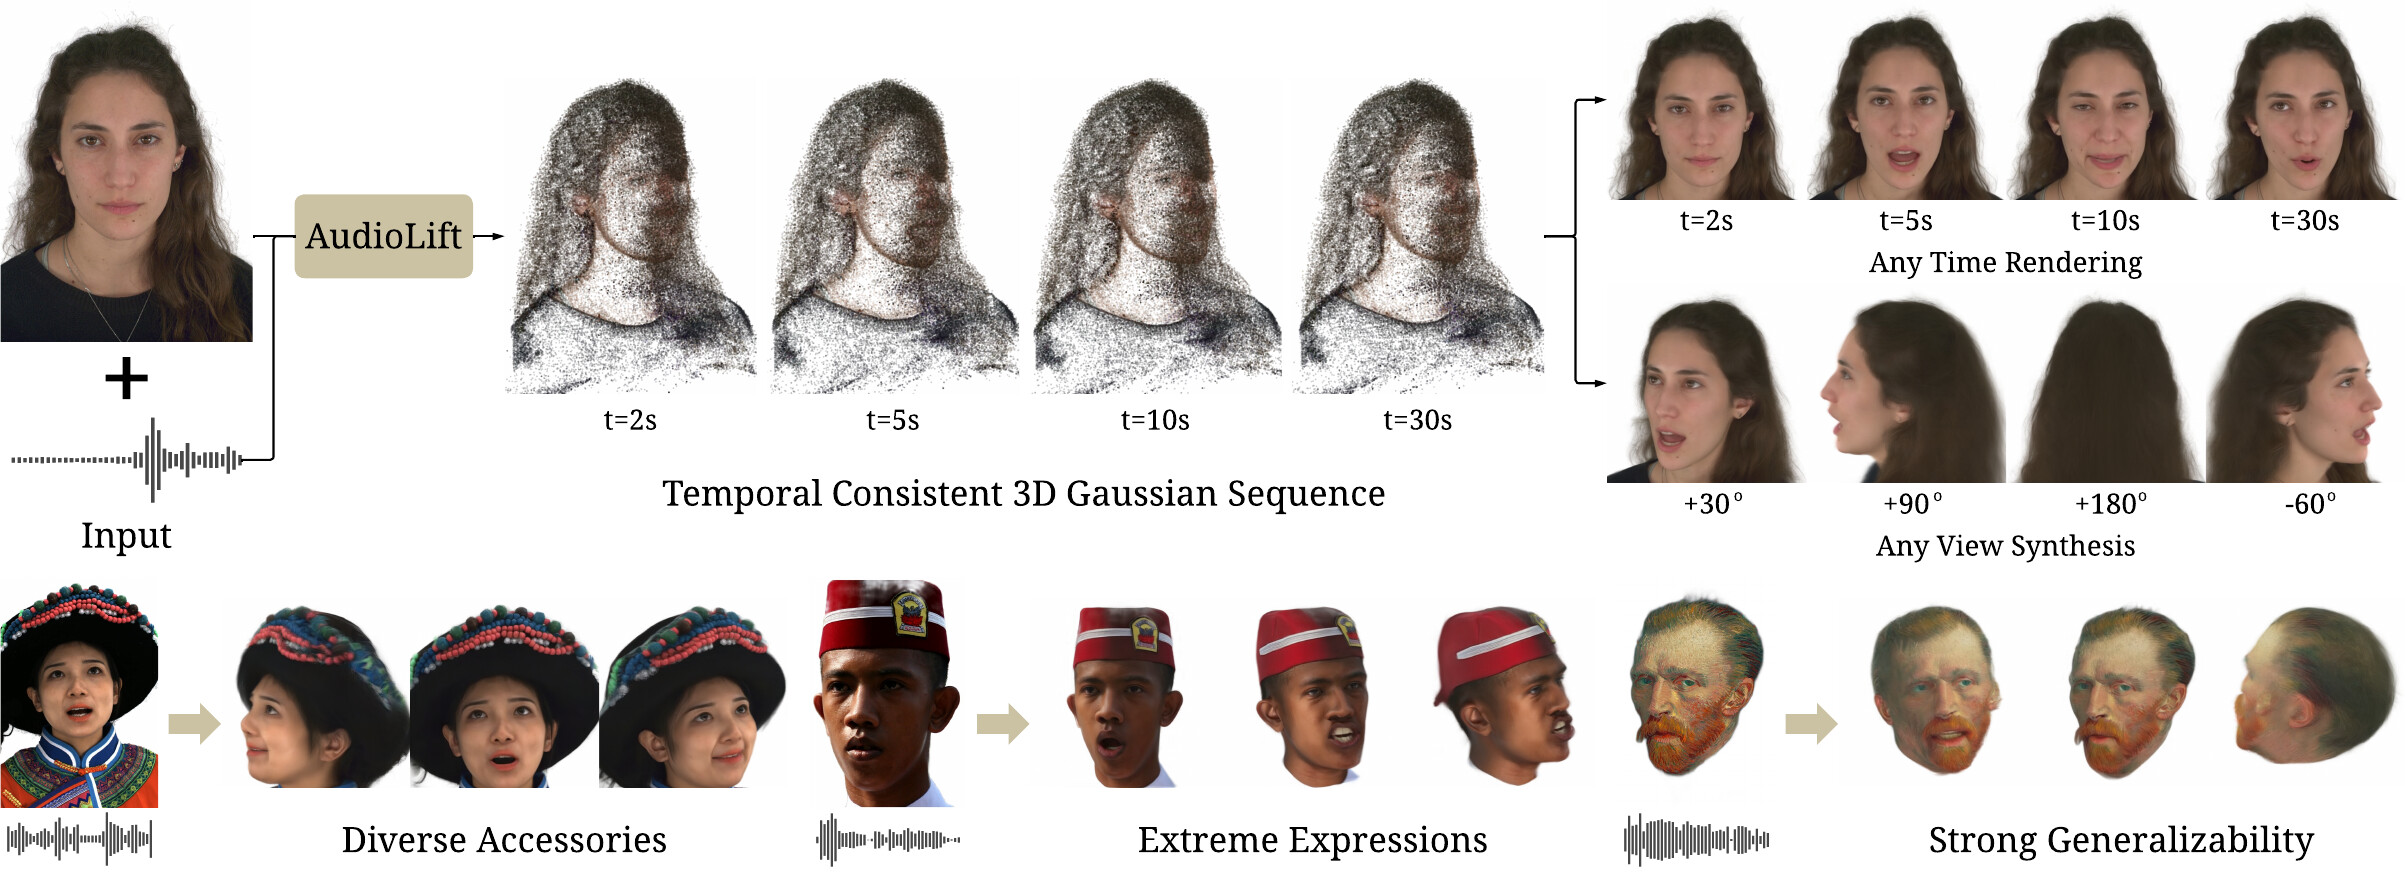
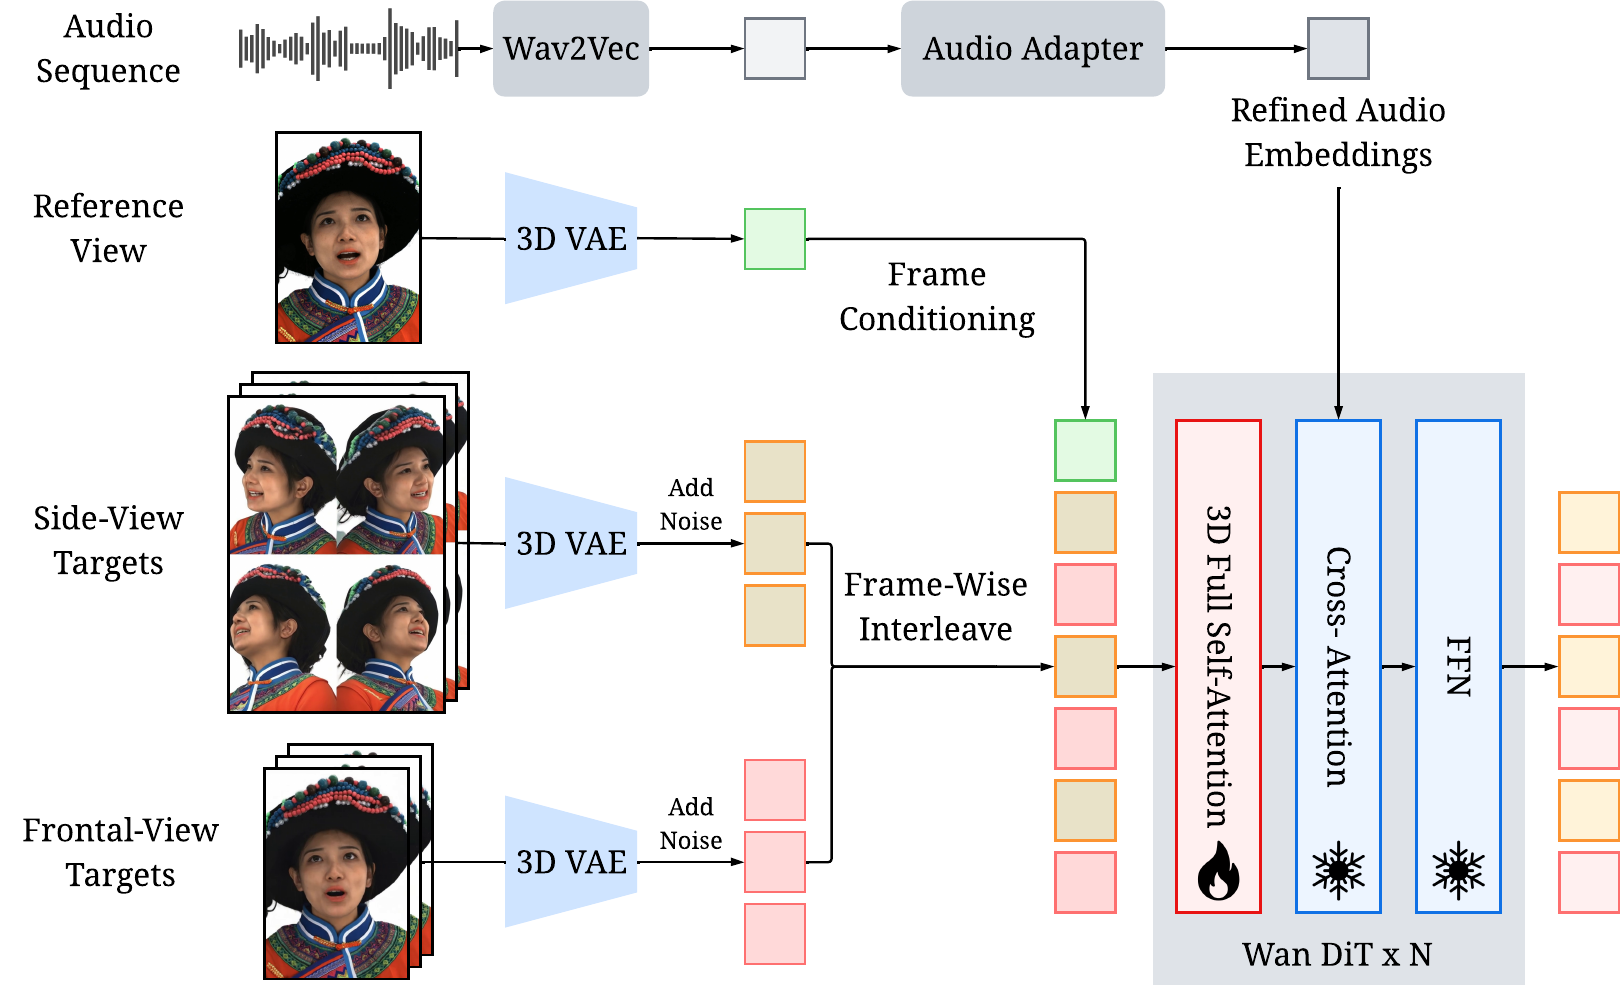
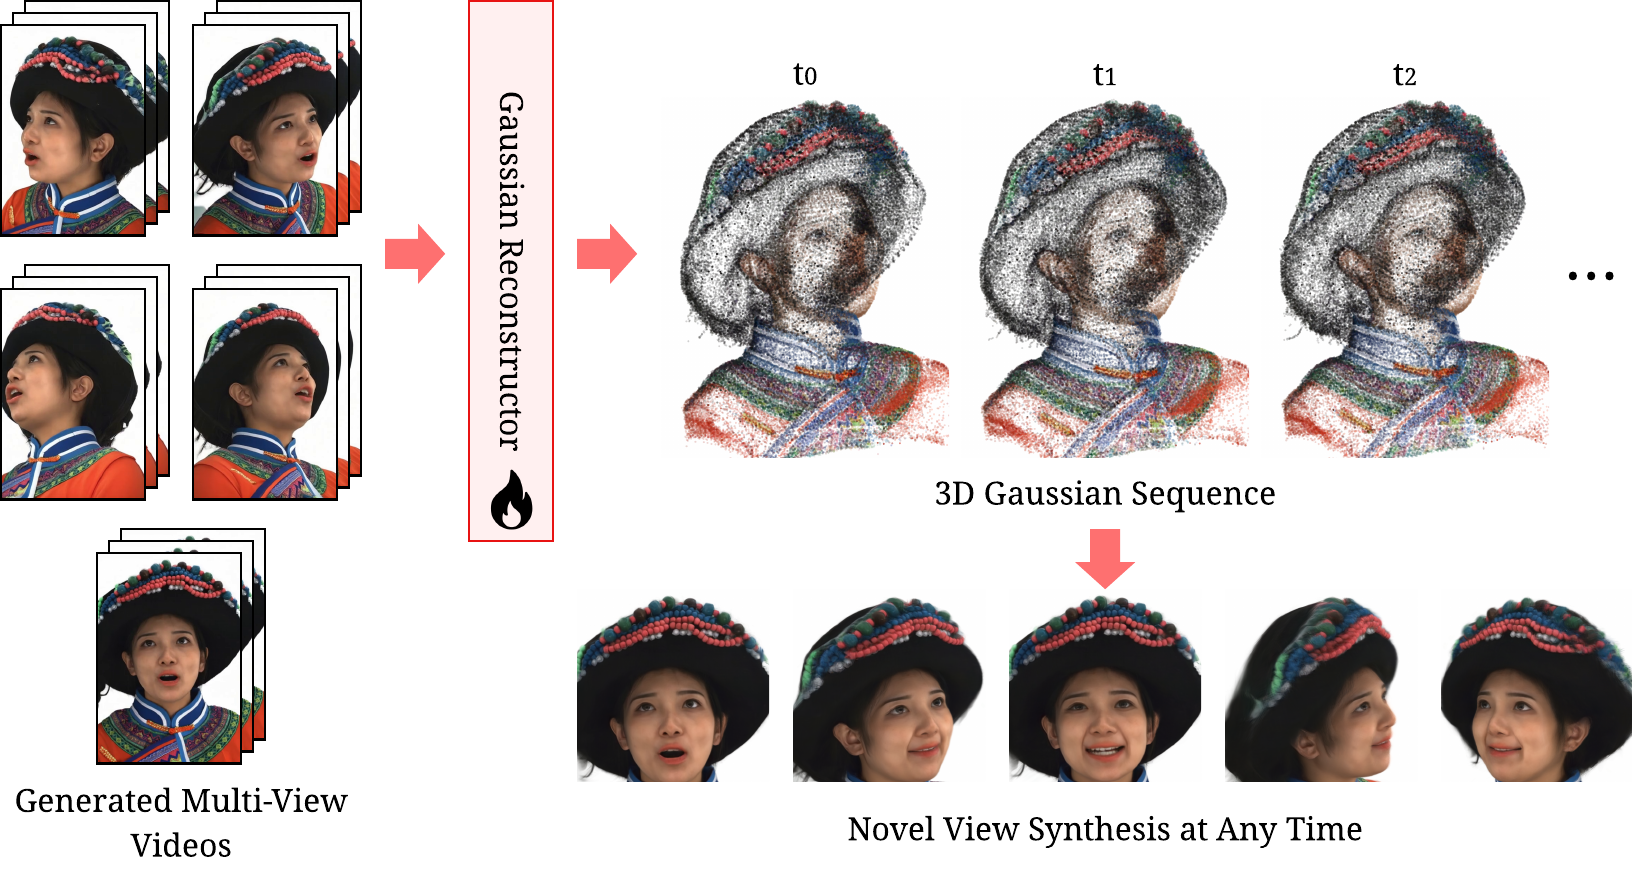
Existing 3D talking avatar methods mainly rely on parametric face models including 3DMM or FLAME, whose compact motion representations limit the models' ability to synthesize extreme expressions and to model facial accessories. We introduce AudioLift, a two-stage framework that uses generated multi-view videos as the intermediate representation for audio-driven avatar generation without parametric face models or per-instance optimization. Our framework combines a synchronized multi-view video generation stage with an inconsistency-robust Gaussian reconstruction stage to recover coherent full-head geometry from a single portrait image. Extensive experiments demonstrate that AudioLift produces 3D talking avatars capable of capturing more extreme facial expressions than existing methods, with improved geometric completeness and strong multi-view consistency across the full 360° viewing range.
12:13 · narrated overview, then results with the original speech
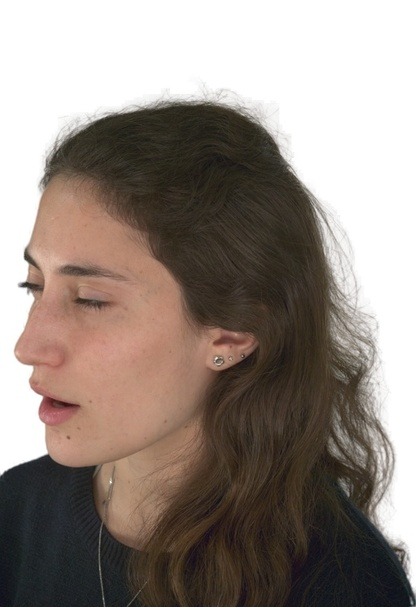 Original source view
One of the four non-anchor source views of a training scene, as captured. The anchor view is never corrupted.
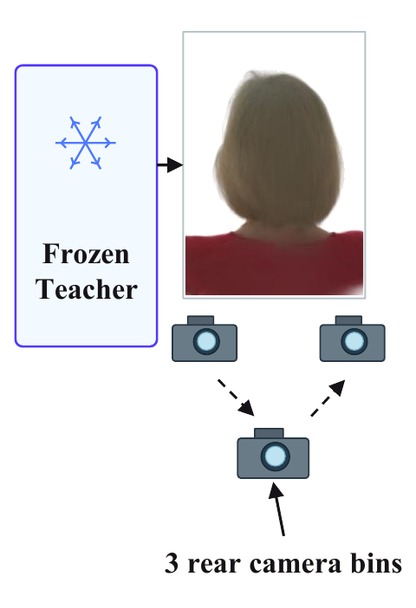 Rear-view distillation
No camera sees the back of the head, so a frozen pretrained teacher renders it from three rear viewpoints and those renders supervise the student.
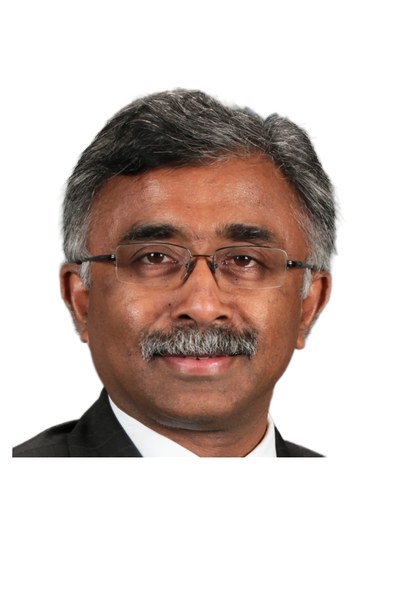
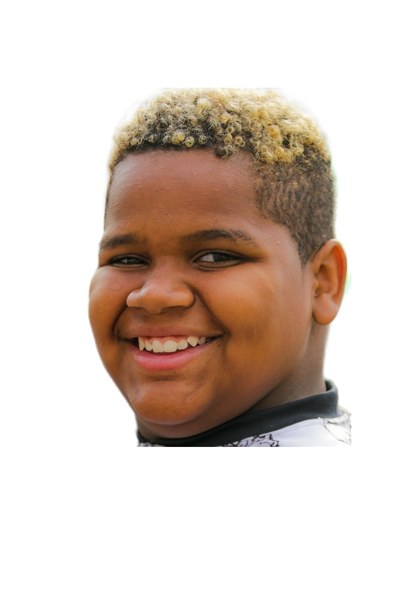
In-the-wild portraits driven by real recordings at their natural length. For every subject the same Gaussian avatar sequence is rendered from the front and from a moving camera: a full turn around the head, or a sweep across the viewing range the training cameras cover. Videos autoplay muted; Audio unmutes one subject at a time.
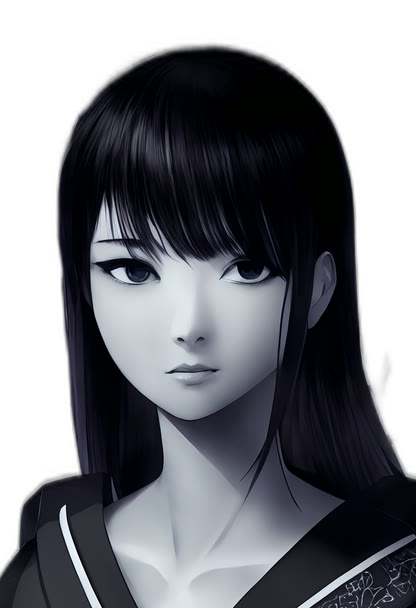 Subject 01 · input
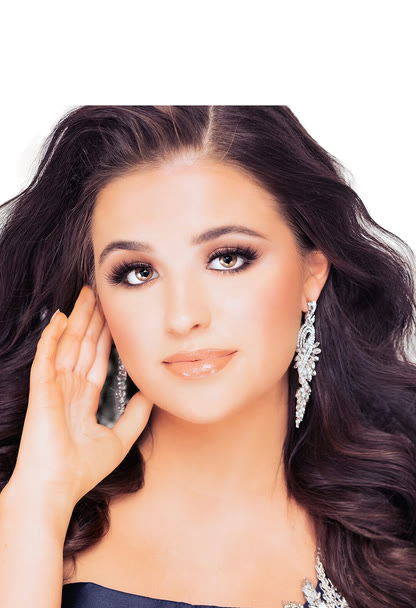 Subject 02 · input
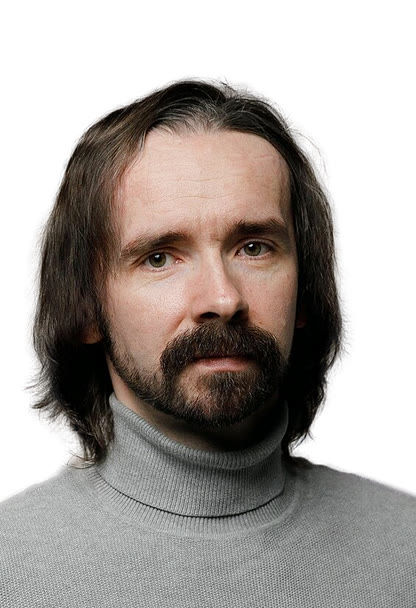 Subject 03 · input
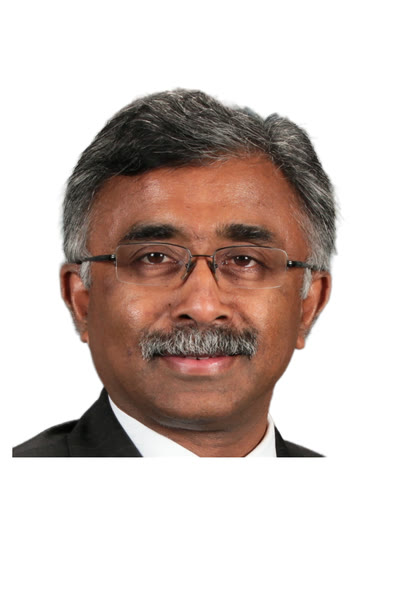 Subject 07 · input
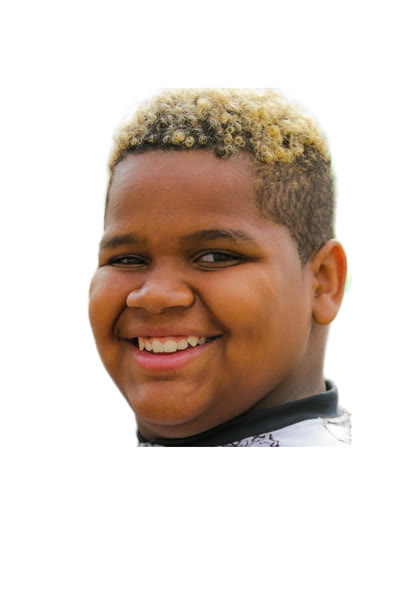 Subject 08 · input
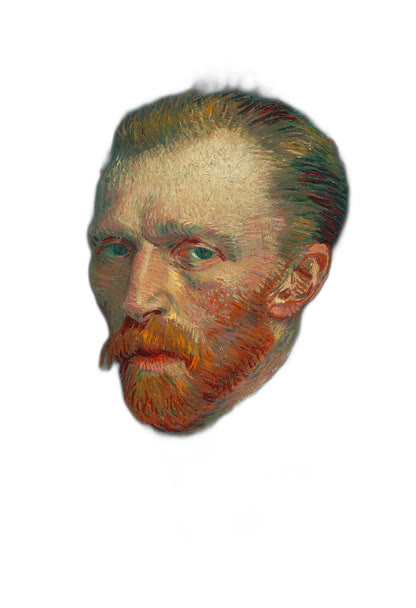 Subject 10 · input
Single portrait + real recording → talking avatar. Top row: frontal rendering. Bottom row: camera demo (coverage sweep, then the final frame is frozen and orbited 360° with a pitch nod). Baselines: Real3D-Portrait, SDTalk and NeRFFaceSpeech, driven by the same image and audio. Videos autoplay muted; Play with audio unmutes the Ours column of that row.
@misc{jiang2026audiolift,
  title  = {AudioLift: Audio-Driven Single Image to Full-Head Gaussian Avatar via Multi-view Video Generation},
  author = {Jiang, Zhuoyuan and Lyu, Weijie and Wang, Xiaoyuan and Shen, Tiancheng and Yang, Ming-Hsuan},
  year   = {2026},
}