|
I am a machine learning researcher at the Vision and Learning Lab at the University of California, Merced, advised by Prof. Ming-Hsuan Yang, where I work on avatars, 3D/4D generation, and video generation. I received my M.S. in Biostatistics (Data Science Pathway) from Yale University in 2026. Before that, I received my B.S. in Psychological & Brain Sciences and Financial Mathematics & Statistics from the University of California, Santa Barbara in 2023, where I was advised by Prof. Michael Ludkovski and Prof. Mary Hegarty. My research interests include multimodal learning, 3D/4D generation, avatars, and vision-language models. Email / Resume / GitHub / Hugging Face / LinkedIn |
|
|
I am looking for full-time Machine Learning Engineer, Research Engineer, and Research Scientist positions. If you think I might be a good fit, or would simply like to connect, please feel free to reach out at zhuoyuan.jiang625@gmail.com. Thanks! |
|
|
|
|
|
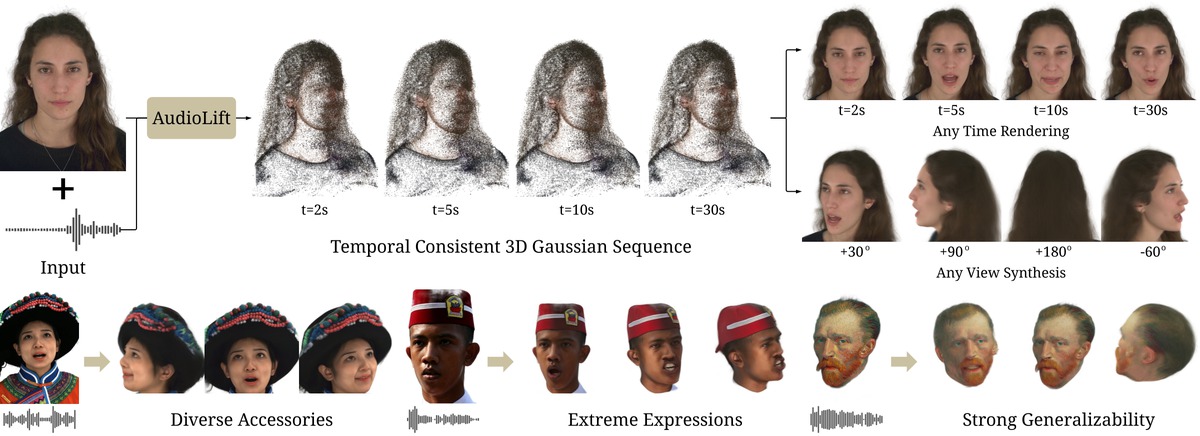
Zhuoyuan Jiang, Weijie Lyu, Xiaoyuan Wang, Tiancheng Shen, Ming-Hsuan Yang Preprint, 2026 Project Page / Video Generalizable single-image to 4D talking avatar without parametric face models or per-subject optimization. |
|
|
|
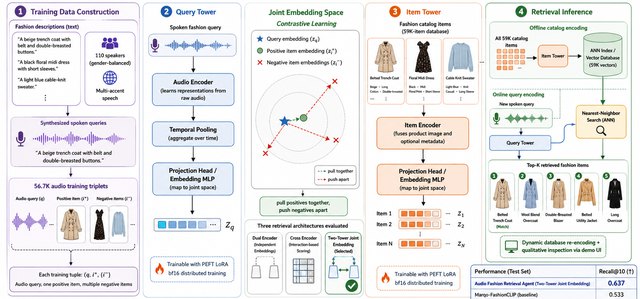
2026 Code / Model An audio-native composed fashion retrieval system: show a garment, speak a modification, and get the matching item from the database. |
|
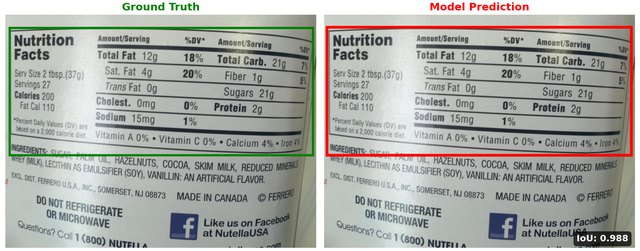
2025 Code / Model Qwen2-VL-7B fine-tuned with 4-bit QLoRA to localize nutrition-facts tables on food packaging, then quantized to GPTQ INT4 and deployed on NVIDIA Triton with a vLLM backend. |
|
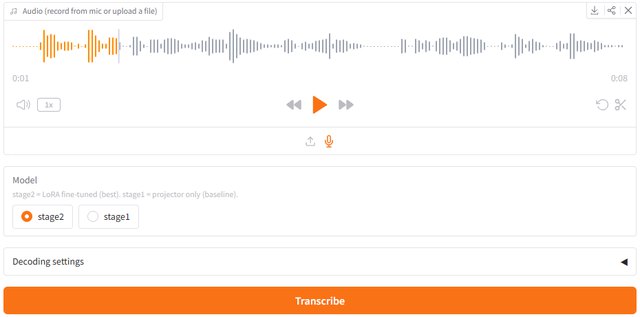
2025 Code / Model An omni model that extends Qwen2-VL-7B with speech understanding: an audio-vision-language model. |
|
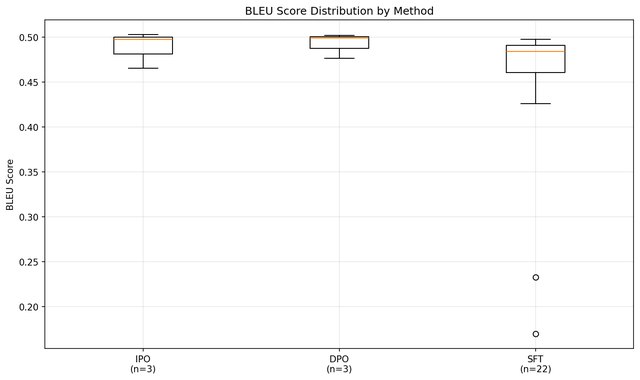
2025 Code / Model A 135M-parameter grammar-correction model that fixes only the errors and keeps the writer's voice instead of rewriting the sentence. |
|
|
|
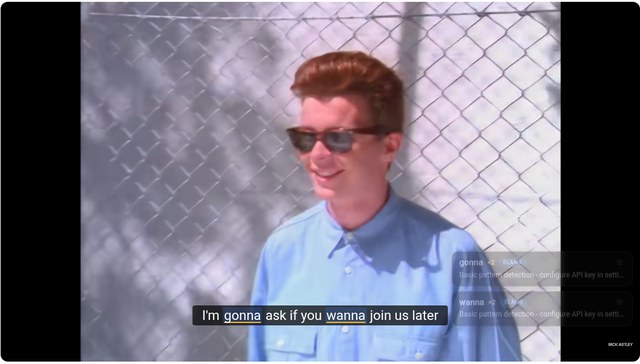
Startup project, Apr. 2025 – Present A Chrome extension that helps non-native English speakers learn slang, phrasal verbs, and cultural references while watching YouTube, with real-time AI detection and explanations on the video. |
|
Updated Oct. 2026. Template from Jon Barron |